Streaming from Event Streams to PostgreSQL: JDBC Sink Connector
Sampoorna Varshinii M.K.S
Technical Support Specialist – MQ & Event Automation
This technical note focuses on demonstrating how discussing the integration of event streams with database by configuring a Kafka Connect JDBC Sink Connector to reliably consume those events, transform them on the fly, and persist them into a PostgreSQL database running on OpenShift Container Platform (OCP).
By the end you will have a working pipeline that consumes events from a Kafka topic, applies Single Message Transforms (SMTs) to shape the payload, and writes each record to a Postgres table.
Key Components: Kafka Connect with JDBC Sink plugin, PostgreSQL Database, and IBM Event Streams (Kafka). In the examples below, I have used version: OpenShift 4.19.26, deployed instances of IBM Event Streams 12.2.2 and a persistent PostgreSQL instance, plus the oc CLI and keytool 11.0.30 utilities.
Architectural overview
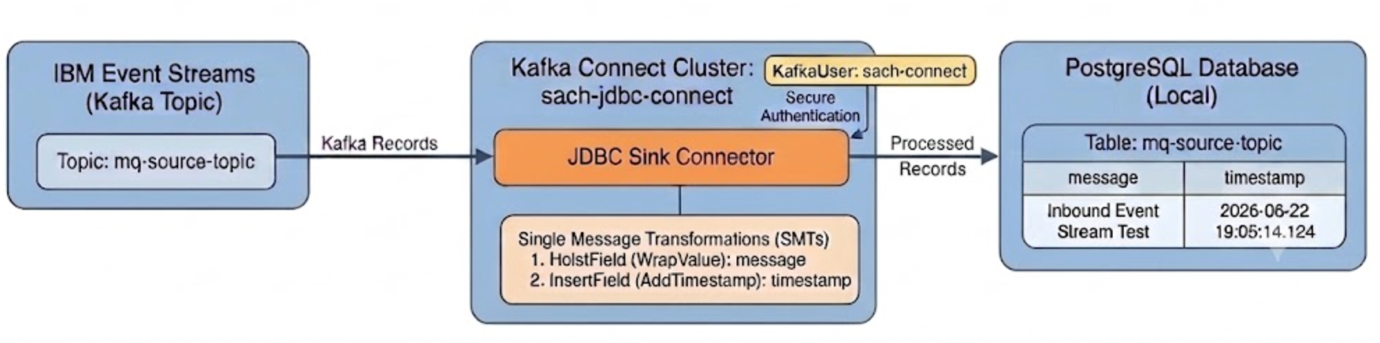
The message is assumed to be published to Kafka as a byte array with a null key and the original message as the value, and is sent to the configured. Once the message reaches Kafka, Single Message Transforms (SMTs) are applied to structure and enrich the payload. The raw message is first wrapped into a JSON object, after which additional fields, such as a timestamp, are appended. The transformed message is then consumed by the sink connector and written to the PostgreSQL database, where the JSON fields are mapped to the corresponding table columns.
For authentication configuration you can refer:
https://ibm.github.io/event-automation/es/security/managing-access/#managing-access-to-kafka-resources
JDBC Sink Connector Setup
Step 1: Create a Kafka Connect cluster for JDBC
1a. Create a KafkaConnect custom resource on OCP.
apiVersion: eventstreams.ibm.com/v1beta2
kind: KafkaConnect # kafka connect
metadata:
annotations:
# ...
name: sach-jdbc-connect # name of the JDBC kafka connect
managedFields:
# ...
namespace: test-ns # namespace in which the connect is being configured
spec:
# ...
type: imagestream
plugins: # refer to the description below
- artifacts:
- type: zip
url: 'https://github.com/Aiven-Open/jdbc-connector-for-apache-kafka/releases/download/v6.10.0/jdbc-connector-for-apache-kafka-6.10.0.zip'
name: postgres-connect-plugin
- artifacts:
- type: jar
url: 'https://jdbc.postgresql.org/download/postgresql-42.7.3.jar'
name: postgres-jdbc-driver
Refer to the plugins part here carefully. This configuration defines the set of plugins required for the Kafka Connect environment to enable integration with external systems.
• It includes a PostgreSQL connector plugin, packaged as a ZIP artifact, which provides the necessary functionality to stream data between Kafka and a PostgreSQL database.
• Additionally, a PostgreSQL JDBC driver is included as a JAR file to facilitate database connectivity.
Together, these plugins ensure that Kafka Connect is equipped to process, transform, and persist data effectively across the defined pipeline.
For details on each of the field and its values, refer https://ibm.github.io/event-
automation/es/connecting/setting-up-connectors/#use-the-event-streams-operator
Refer to the connect catalog to get the correct type and the url:
https://ibm.github.io/event-automation/connectors/kc-sink-jdbc-aiven/installation
1b. Apply the configuration:
oc apply -f jdbc-kafka-connect.yaml
1c. Verify Kafka Connect status:
oc get kafkaconnect <jdbc-connect-cluster-name> -n <namespace>
Step 2: Set up PostgreSQL on OCP
Before creating the connector instance, you need a running PostgreSQL deployment.
2a. To set up PostgreSQL:
oc new-app postgresql-persistent \
-p POSTGRESQL_USER=<db-username> \
-p POSTGRESQL_PASSWORD=<db-password> \
-p POSTGRESQL_DATABASE=<db-name> \
-p VOLUME_CAPACITY=1Gi \
-n <namespace>
>oc new-app postgresql-persistent -p POSTGRESQL_USER=testuser -p POSTGRESQL_PASSWORD=testpass -p POSTGRESQL_DATABASE=testdb -p VOLUME_CAPACITY=1Gi -n test-ns
2b. Confirm the pod is running and note the service name:
oc get pods -n <namespace> | grep postgresql
oc get svc postgresql -n <namespace>
>oc get pods -n test-ns | grep postgresql
postgresql-1-deploy 0/1 Completed 0 47s
postgresql-1-flkrh 1/1 Running 0 43s
>oc get svc postgresql -n test-ns
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
postgresql ClusterIP 172.30.24.250 <none> 5432/TCP 5
Step 3: Create the JDBC Sink Connector instance
3a. Describe the PostgreSQL service to find the cluster-internal hostname and port:
>oc describe svc postgresql -n test-ns
Name: postgresql
Namespace: test-ns
Selector: name=postgresql
Type: ClusterIP
IP Family Policy: SingleStack
IP Families: IPv4
IP: 172.30.24.250
IPs: 172.30.24.250
Port: postgresql 5432/TCP
TargetPort: 5432/TCP
Endpoints: 10.254.21.160:5432
The JDBC URL follows this pattern:
jdbc:postgresql://<service-name>.<namespace>.svc.cluster.local:<port>/<database>
>For example:
jdbc:postgresql://postgresql.my-namespace.svc.cluster.local:5432/testdb
Host: postgresql.test-ns.svc.cluster.local; Port: 5432; Database: testdb
3b. Connector configuration
A minimal `jdbc-sink-connector.yaml` looks like this:
apiVersion: eventstreams.ibm.com/v1beta2
kind: KafkaConnector
metadata:
name: jdbc-sink-connector
labels:
eventstreams.ibm.com/cluster: <jdbc-connect-cluster-name>
spec:
class: io.aiven.connect.jdbc.JdbcSinkConnector
tasksMax: 1
config:
topics: mq-source-topic
connection.url: jdbc:postgresql://postgresql.<namespace>.svc.cluster.local:5432/<db-name>
connection.user: < ${file:/mnt/db-username:username}>
connection.password: < ${file:/mnt/db-credentials:password}>
# Write mode — insert a new row for every message
insert.mode: insert
# Auto-create the target table from the record schema (disabled by default)
auto.create: true
# Converter must have schemas enabled so the connector knows the field types
value.converter: org.apache.kafka.connect.json.JsonConverter
value.converter.schemas.enable: "true"
# SMTs: wrap the raw value in a struct, then add a timestamp field
transforms: wrapValue,addTimestamp
transforms.wrapValue.type: org.apache.kafka.connect.transforms.HoistField$Value
transforms.wrapValue.field: payload
transforms.addTimestamp.type: org.apache.kafka.connect.transforms.InsertField$Value
transforms.addTimestamp.timestamp.field: event_timestamp
This configuration defines a Kafka Connect JDBC sink connector that consumes messages from the mq-source-topic Kafka topic and writes them to a PostgreSQL database. Before the data is persisted, SMTs wrap the incoming message into a structured JSON object and add a timestamp field. The connector is configured to insert records, automatically create the target table if it does not exist, and connect to PostgreSQL using the specified JDBC connection details, ensuring that the transformed messages are stored in a structured and queryable format.
Note: The connector supports four insertion modes: insert, multi, upsert, and update. Refer document
3c. Apply the JDBC Sink Connector:
oc apply -f jdbc-sink-connector.yaml
3d. Verify it is running:
oc get kafkaconnector jdbc-sink-connector -n <namespace>
oc get kafkaconnector jdbc-sink-connector -n <namespace> \
-o jsonpath='{.status.connectorStatus.connector.state}'
Example:
>oc get kafkaconnector jdbc-sink-test -n test-ns
NAME CLUSTER CONNECTOR CLASS MAX TASKS READY
jdbc-sink-test sach-jdbc-connector io.aiven.connect.jdbc.JdbcSinkConnector 1 True
>oc get kafkaconnector jdbc-sink-test -o jsonpath='{.status.connectorStatus.connector.state}'
RUNNING%
You want to see `RUNNING`. If you see `FAILED`, check the Kafka Connect pod logs first.
TESTING
To validate the end-to-end streaming pipeline, incoming records must first reside in the designated IBM Event Streams (Kafka) topic, regardless of the source application connected to the cluster.
IBM MQ publishes messages to a queue. An MQ Source Connector moves those messages into a Kafka topic(mq-source-topic) in Event Streams. From there, the JDBC Sink Connector picks them up and writes them to Postgres. The sink connector needs structured, schema-aware records, so SMTs sit in the middle to wrap raw bytes into a JSON object and attach a timestamp field before the records reach the connector.
STEP1: Send a message to MQ
Here for testing, I have put 2 messages: ‘testing connector configuration’ ,‘end to end flow success!!’, as below.
>sh-5.1$ dspmq
QMNAME(sachmq) STATUS(Running)
>sh-5.1$ /opt/mqm/samp/bin/amqsput DEV.QUEUE.1 sachmq
Sample AMQSPUT0 start
target queue is DEV.QUEUE.1
testing connector configuration
end to end flow Success!!
STEP 2: Verify the message arrived in Event Streams
2a. Open the Event Streams UI (the link appears on the right-hand side of the ES instance page in OCP).
2b. Log in with the Kafka user you configured. To get the password, navigate to the Kafka user's resources section and scroll down to copy it.
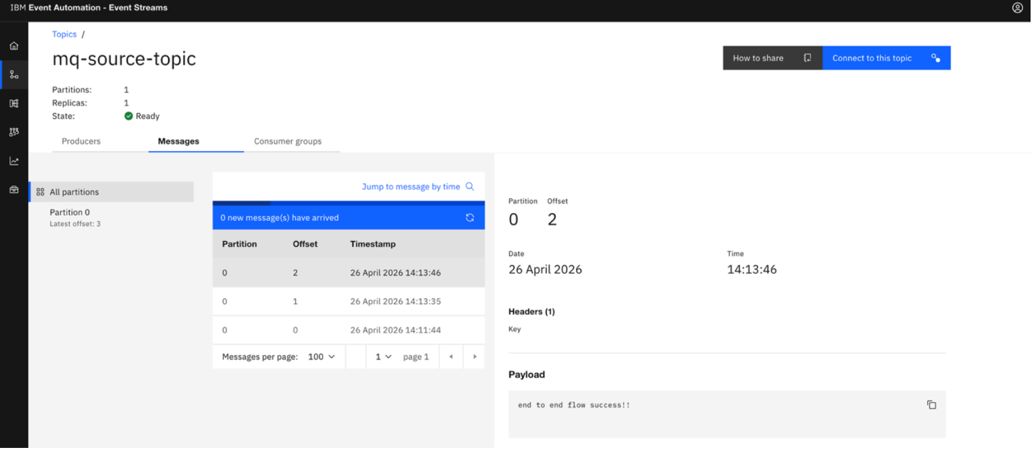
2c. Select Topics from the left menu, open mq-source-topic, go to the Messages tab, and refresh. Your test message should appear as shown below.
STEP 3: Query PostgreSQLQuery
To check if the data from the kafka topic has been inserted into the target database.
3a. Using OC CLI:
• List all tables:
oc exec <postgresql-pod-name> -n <namespace> -- \
psql -U <db-username> -d <db-name> -c "\dt"
> oc exec postgresql-1-flkrh -n test-ns -- psql -U testuser -d testdb -c "\dt"
List of relations
Schema | Name | Type | Owner
-------------+------------------+-------+------------
public | mq-source-topic | table | testuser
(1 row)
• View all rows in the target table:
oc exec <postgresql-pod-name> -n <namespace> -- \
psql -U <db-username> -d <db-name> -c 'SELECT * FROM "<table-name>";'
> oc exec postgresql-1-flkrh -n test-ns -- psql -U testuser -d testdb -c 'SELECT * FROM "mq-source-topic";'
message | timestamp
------------------------------------------------------+-------------------------
helooooo!! this is sam here! | 2026-03-18 17:35:14.091
hi | 2026-03-18 17:41:49.742
test1 | 2026-03-18 17:41:52.502
test2 | 2026-03-18 17:41:54.882
hi there! testing connect! | 2026-04-21 13:56:17.289
{"orderId":"21","price":300,"product":"laptop"} | 2026-04-22 04:34:38.14
{"orderId":"5","price":140,"product":"keyboard"} | 2026-04-22 04:35:25.863
{"orderId":"24","price":330,"product":"monitor"} | 2026-04-22 04:35:35.671
Test message from MQ | 2026-04-26 08:41:44.076
testing connector configuration | 2026-04-26 08:43:35.275
end to end flow success!! | 2026-04-26 08:43:46.657
(11 rows)
• View latest messages
oc exec <postgresql-pod-name> -n <namespace> -- \
psql -U <db-username> -d <db-name> \
-c 'SELECT * FROM "<table-name>" ORDER BY event_timestamp DESC LIMIT 5;'
> oc exec postgresql-1-flkrh -n test-ns -- psql -U testuser -d testdb -c 'SELECT * FROM "mq-source-topic" ORDER BY timestamp DESC LIMIT 5;'
message | timestamp
------------------------------------------------------+-------------------------
end to end flow success!! | 2026-04-26 08:43:46.657
testing connector configuration | 2026-04-26 08:43:35.275
Test message from MQ | 2026-04-26 08:41:44.076
exit | 2026-04-22 04:39:47.333
{"orderId":"24","price":330,"product":"monitor"} | 2026-04-22 04:35:35.671
(5 rows)
3b. Using OCP UI:
1. Go to Workloads → Pods, find the PostgreSQL pod, and open Terminal.
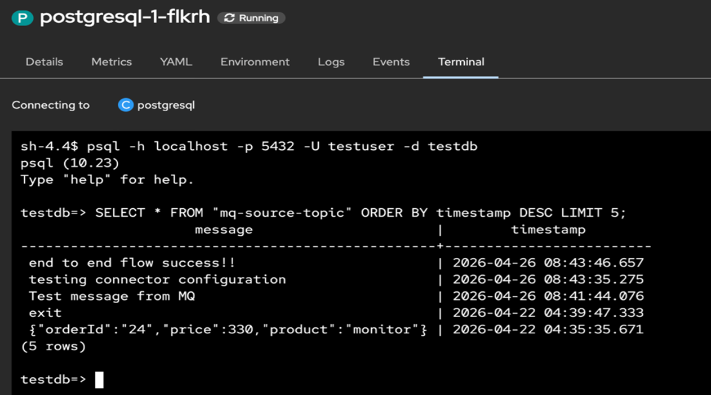
2. Connect to the database: psql -h localhost -p 5432 -U <db-username> -d <db-name>
3. Run your query: SELECT * FROM "mq-source-topic" ORDER BY event_timestamp DESC LIMIT 5;