Enhancing data quality with broker-side validation
As integration developers, we know the importance of data quality. Only one event which is non-compliant with the schema can have a huge impact. Even more so in an event-driven integration where one ‘rogue event’ can impact all subscribed consumers, break applications and eventually damage the trust-factor of your core event structure.
To avoid this, we use schemas and schema enforcements through the schema registry. A schema registry (which is a standalone server with the sole purpose of storing schemas for Kafka topics) enables centralized schema management, compatibility enforcement, governance and self-service.
So far, my experiences on projects have been with client-side validation. Which provides actionable error feedback, making it easier for the development team to debug and fix issues with invalid data. It also facilitates the fail-fast concept where the producing application catches the error before sending it to the Kafka topic. However, I’ve also experienced that the consuming application is very dependent on the quality of data (and validation) the producer implements. If the producer does not take schema validation seriously, it can still break the consuming application.
How does client-side validation work?
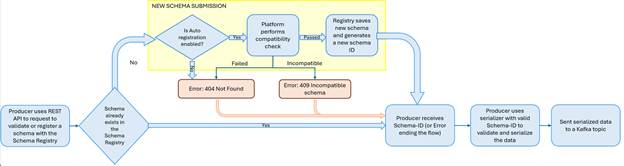
Simply taken, these are the steps required for client-side validation and publication of events.
Possible pitfalls
The primary risk of client-side validation is that it remains optional. The Kafka topic does not enforce any type of schema validation. So, if the producing application does not do any validation, it will still be able to produce events to the topic.
But let’s assume that the developers of the producing application implemented schema validation. Several risks remain:
· Version mismatch: A new version of the schema has been provided but the producer or consumer have not synced to the newer version causing issues during serializing and/or deserializing the events on the topic.
· Not using a Schema Registry SerDe: a producer can opt to use a StringSerializer or a ByteArraySerializer. This will result in plain text or raw bytes being pushed to Kafka without the schema ID. Causing any consumer using the schema registry for validation to be unable to process the event using a schema to deserialize.
· Relaxed SerDe configurations: Client-side libraries can be reconfigured to loosen or even bypass client-side validation.
Event Endpoint Management: broker-side validation to save the day
The easiest way to guarantee the data integrity of your events on your Kafka topics is by shifting the validation process from an untrusted client to a trusted broker. This capability is precisely what IBM Event Endpoint Management(EEM) provides in the form of controls to your topic subscribers.
Instead of providing direct access to your Kafka topics (on Confluent or any other Kafka platform). We will route all traffic through an event gateway. This gateway will manage traffic and is able to enforce restrictions/rule-sets on all producers and consumers in the form of policies (options). More info on options can be found here: https://ibm.github.io/event-automation/eem/describe/managing-options/.
There are several types of control actions that can be assigned to an option:
· Approval
· Mutual TLS
· Schema enforcement
· …
This specific control enforces the producer can only produce events matching the schema. If the producer wants to send an event which is not compatible with the schema, it will be rejected.
Demo
Prepare the demo environment
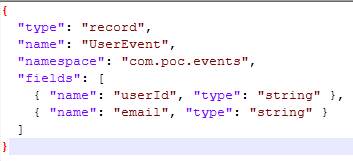
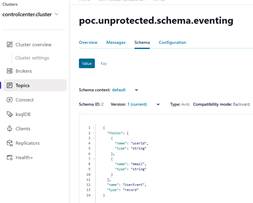
I’m using a simple Avro schema to validate the events I’ll be sending:
I’m running a simple setup of Confluent on my laptop. To simplify the setup, I’ve created three topics:
· poc.unprotected.eventing
· poc.unprotected.schema.eventing (providing a schema in the schema registry)
· poc.protected.eventing (protected by IBM Event Endpoint Management)
I’m using python scripts to create different producers supporting my cases. I’ll share parts of the code to show what I’m doing. Important: The code shown is quickly made without any intention of promoting it to any other environment than this demo. So, it is not production ready by any means.
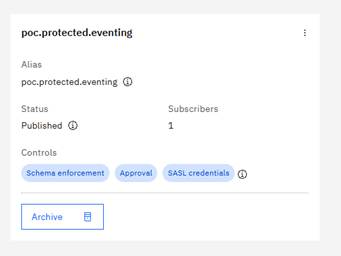
For the third use case, I’ve installed an IBM Event Endpoint Management (EEM) with an Event Gateway on OCP. In EEM I’ve configured my local confluent as a cluster so I can expose my confluent topics in my portal and add security and validation options. Options configured:
· Schema validation
· SASL credentials
In my demo I’ll be showcasing 3 use cases:
Case 1:
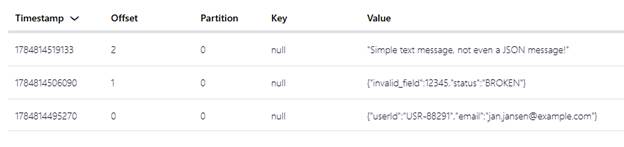
A valid and invalid message produced directly to the Kafka topic proving I can send anything I like to the Kafka topic. Kafka won’t do any validation for me.
Case 2:
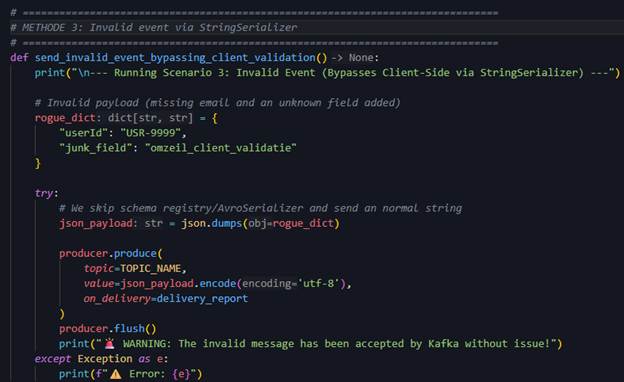
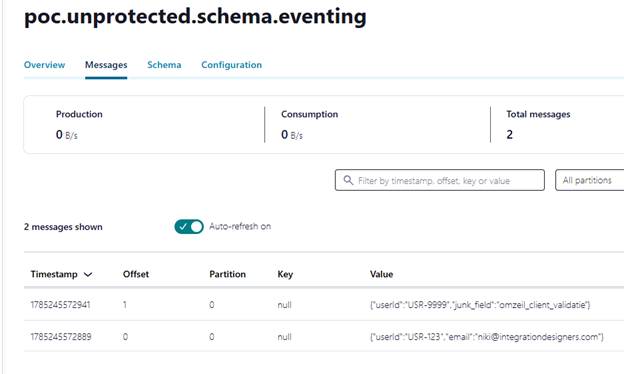
Even though we have registered a schema, using the StringSerializer, we can still send events to the topic. Using the AvroSerializer, this would have been blocked on client-side.
Risk: Consumers believe it to be safe, but we are still depending on the producer to send valid events.
Case 3:
We put EEM in between and let EEM do event validation using the same schema. Result: Consumers don’t have to rely on the producers providing correct data. The consumers will be protected by the gateway.
CASE 1: Create a topic on Confluent and produce directly to it (No validation)
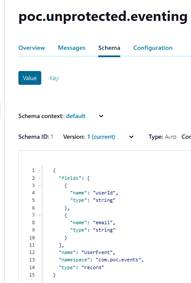
As you will see in the next screenshot. I’m able to send any event I like, even if it is not compliant the schema. Although it seems (as shown in the image) that the schema is linked to the topic. Kafka does not enforce any validation.
Schema:
Command line sending events

Results shown in confluent
Conclusion
This shows how much the consumer relies on the producer to provide high-quality data.
CASE 2: Create a producer with a StringSerializer
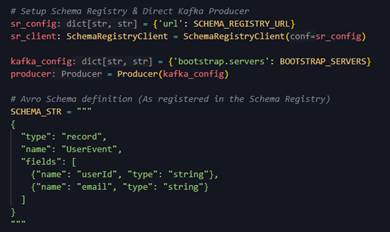
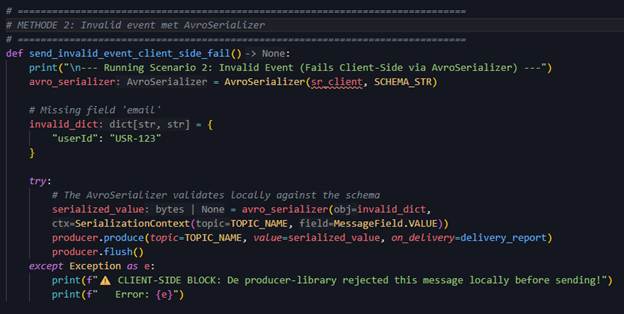
I’ll be sending data using the AvroSerializer and the StringSerializer to show how different the client reacts.
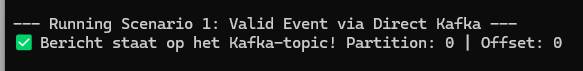
2.1: Send a valid event
Just to prove I can send valid events
2.1 Client side AvroSerializer
Show that when using the Schema Registry and the AvroSerializer, on client side we will be blocked from sending invalid events

2.3: Client side StringSerializer

CASE 3: Create a topic in EEM and add schema enforcement
In this case, we won’t be going directly to the Kafka topic in Confluent, but we will be addressing the topic through an event gateway. This gateway will implement schema validation for us.
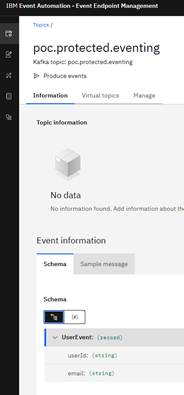
Topic and schema validation configured in EEM:
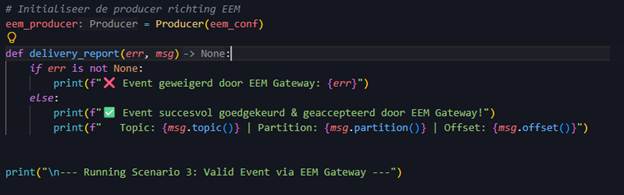
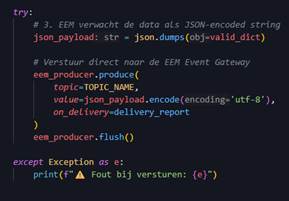
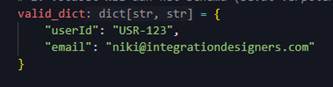
First we will be sending a valid event, next an invalid event
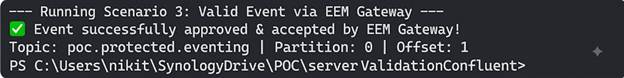
Valid
Invalid

Conclusion
Client-side validation certainly has its advantages as it promotes the fail-fast principle and gives developers early and actionable feedback during development. But as the experiments shown above prove, client-side validation is optional. A producer can accidentally or intentionally bypass the Schema validation and start polluting the Kafka topic with rogue events. Even if 99% of your producers are strictly following the validation rules, one non-compliant event is enough to break downstream consumer applications and break trust in your event broker.
By introducing an Event Gateway using EEM, you shift the responsibility of data validation from an “untrusted” client to a trusted integration layer. With broker-side schema validation we are certain that rogue events are blocked in the gateway and will never reach your Kafka topic.