Co-Authored by @Harisha Paildar
The Watson Enhanced Extraction capability and configuration steps described in this document are applicable to CCX 26.0 and later releases. The user interface, available options, and supported extraction features may vary in earlier versions.
In today's enterprise content management landscape, extracting meaningful information from documents is critical for enabling advanced capabilities like Content-Based Retrieval (CBR), Generative AI, and intelligent search. Traditional text extraction methods often fall short when dealing with complex documents containing images, forms, or embedded content.
IBM FileNet Content Engine 5.8.0 introduces Enhanced Extraction, a powerful feature that goes beyond standard Object Indexing Technology (OIT) by leveraging advanced techniques such as Optical Character Recognition (OCR) and intelligent metadata extraction. Features such as PDF form field extraction, image text recognition, and structured metadata extraction help organizations unlock the full potential of their document repositories.
At the centre of these enhanced capabilities is the Enhanced Extraction framework with pluggable handlers. It acts as the bridge between FileNet P8 and specialised extraction services, including PDFBox for form processing and Watsonx.AI for advanced OCR.
This blog provides an overview of Enhanced Extraction, its purpose, key use cases, and detailed step-by-step instructions on how to enable and configure it in FileNet P8 using the ACCE (Administration Console forContent Platform Engine).
What is Enhanced Extraction?
Enhanced Extraction is a specialised content processing framework introduced by the Enhanced ExtractionExtensions Add-on in FileNet Content Engine 5.8.0. It acts as an extensible mechanism that allows custom handlers to contribute superior text extracts and metadata compared to what is achievable through standardOIT-based extraction.
The framework produces outputs in a special content type (application/x-ibm-enhanced-extract) containing:
-
-
- Text Extract: Plain text extracted from documents with better quality than OIT.
- Metadata Extracts: Structured data such as key-value pairs, tables, and markdown representations.
Once configured, the system automatically applies enhanced extraction to documents, creating annotations that can be used for:
-
-
- CBR Indexing: Full-text search with metadata field indexing.
- GenAI Vector Indexing: Improved semantic search capabilities.
- Summary Generation: Better AI-generated document summaries.
What are PDF Forms Handler and Watson Handler?
PDF Forms Handler
The PDF Forms Handler is an out-of-the-box implementation that utilizes the PDFBox library to extractmetadata from PDF AcroForms (fillable PDF forms). It automatically:
-
-
- Detects PDF forms in your document repository
- Extracts field names and their filled values as key-value pairs
- Provides high-quality text extraction comparable to or better than OIT
- Requires no configuration—works immediately after add-on installation
Watson Handler
The Watson Handler integrates with IBM Watsonx.AI Text Extraction service (or Watson Document Understanding) to provide advanced capabilities:
-
-
- OCR Processing: Extracts text from images and scanned documents
- Intelligent Metadata Extraction: Identifies key-value pairs, tables, and document structure
- Multiple Format Support: Processes PDFs, images, Word documents, and more
- Configurable Processing: Administrators control OCR modes, quality settings, and metadata types
Prerequisites
Before configuring Enhanced Extraction in ACCE, ensure the following requirements are met:
-
-
- FileNet Content Engine: Version 5.8.0 recommended
- Persistent Text Extracts (PTE): Must be enabled—PTE add-on must be installed
- Enhanced Extraction Extension (EEE): Must be enabled – ETE Add-on must be installed
- Administrator Access: Full administrative privileges in ACCE
- ACCE Access: Administration Console for Content Platform Engine installed and accessible
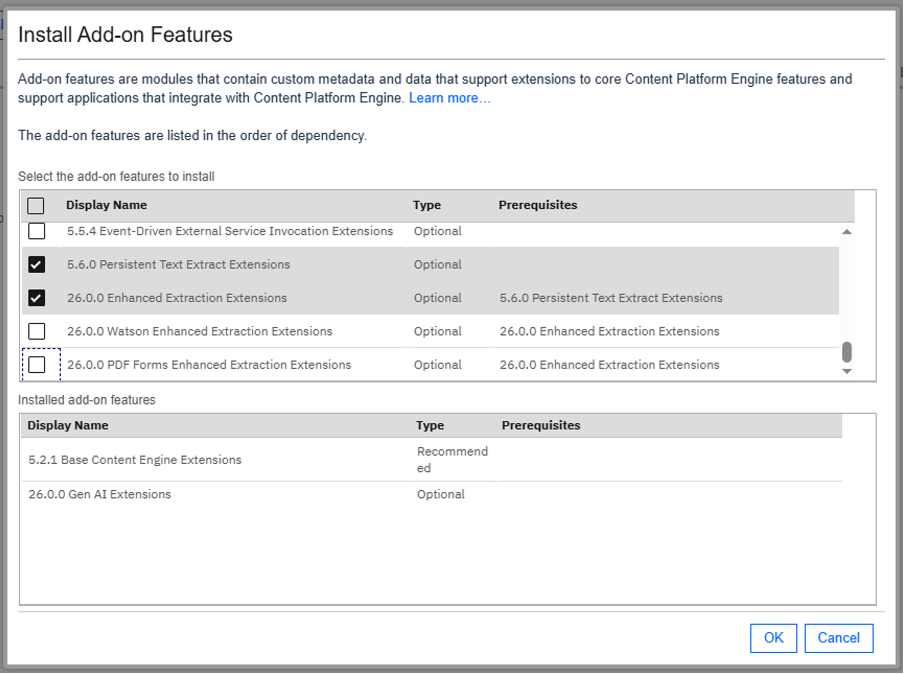
For Watson Handler Configuration
-
-
- Watsonx.AI or WDU Service: Active subscription or deployment
- ICOS Access: IBM Cloud Object Storage bucket configured
- API Keys: Valid authentication credentials for both services
- Network Connectivity: Outbound access to Watsonx.AI and ICOS endpoints
Step-by-Step Configuration of Enhanced Extraction Extension in ACCE
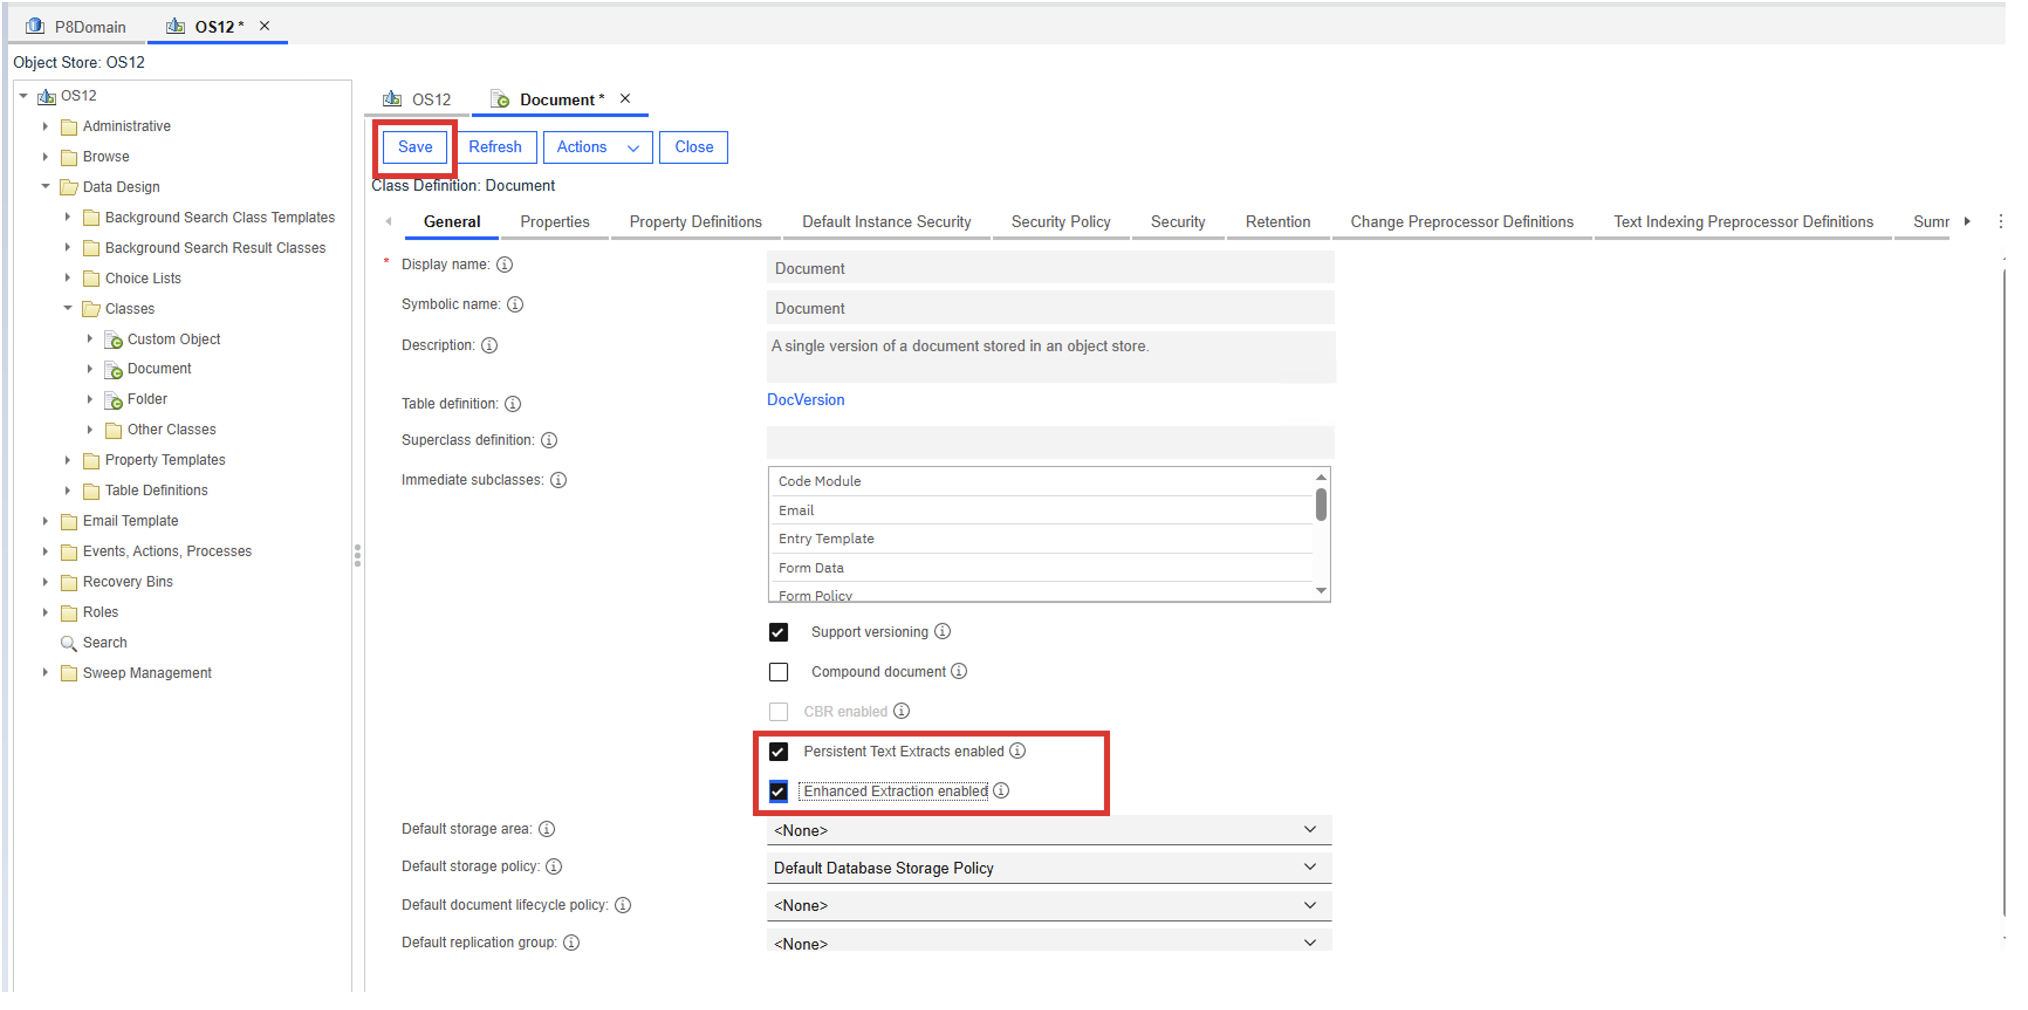
Enhanced Extraction Extension is enabled at the document class level and builds upon Persistent Text Extraction (PTE). Before enabling Enhanced Extraction Extension, Persistent Text Extraction must already be enabled forthe target document class.
Step 1: Navigate to the Document Class
-
- Open your Object Store in ACCE.
- Navigate to Data Design.
- Expand Classes and select the required Document Class.
- Open the document class properties.
- The General tab will be displayed in the right-hand pane.
At this stage, you will notice a new option called Enhanced Extraction Extension Enabled located directly below the Persistent Text Extracts Enabled setting.
Note: Initially, the Enhanced Extraction Enabled checkbox is disabled (greyed out) because Persistent Text Extraction has not yet been enabled.
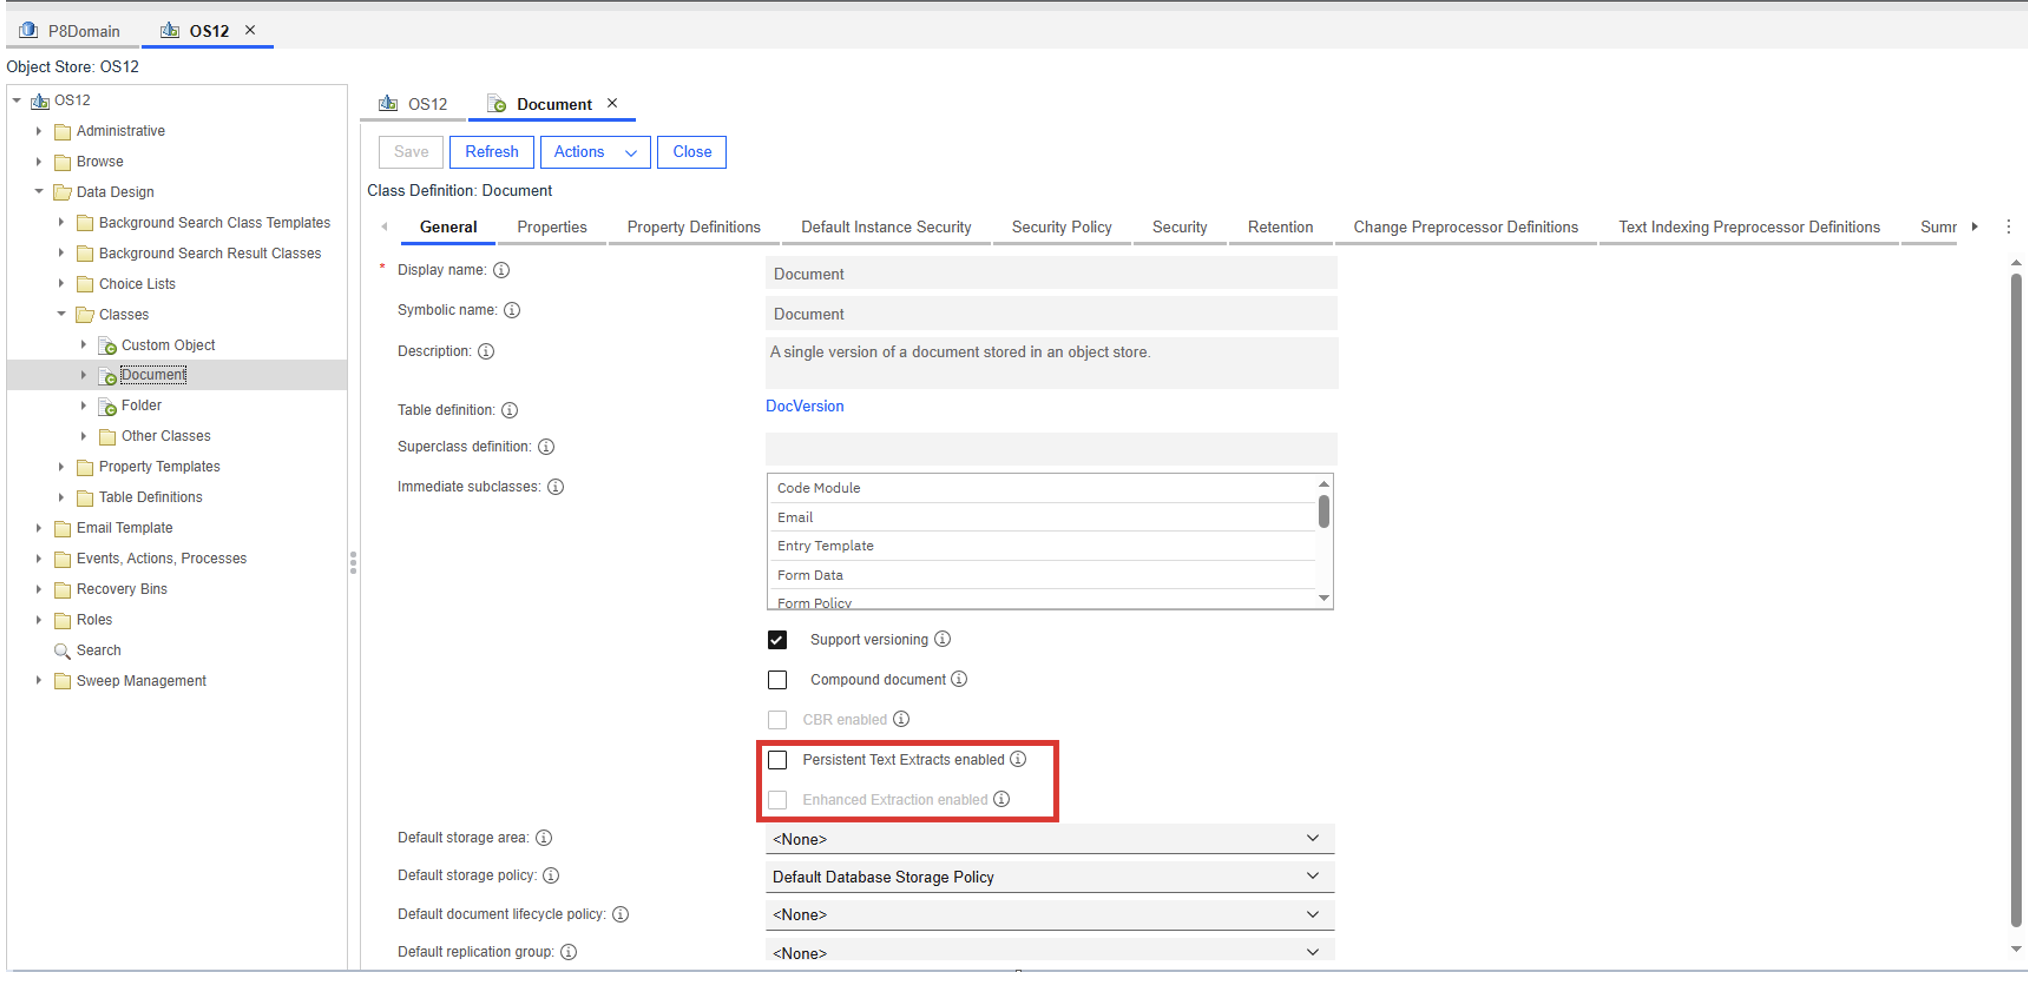
Step 2: Enable Persistent Text Extraction
-
- In the General tab, locate Persistent Text Extracts Enabled.
- Select the checkbox to enable Persistent Text Extraction.
- Once enabled, the Enhanced Extraction Enabled option becomes available and can now be selected.
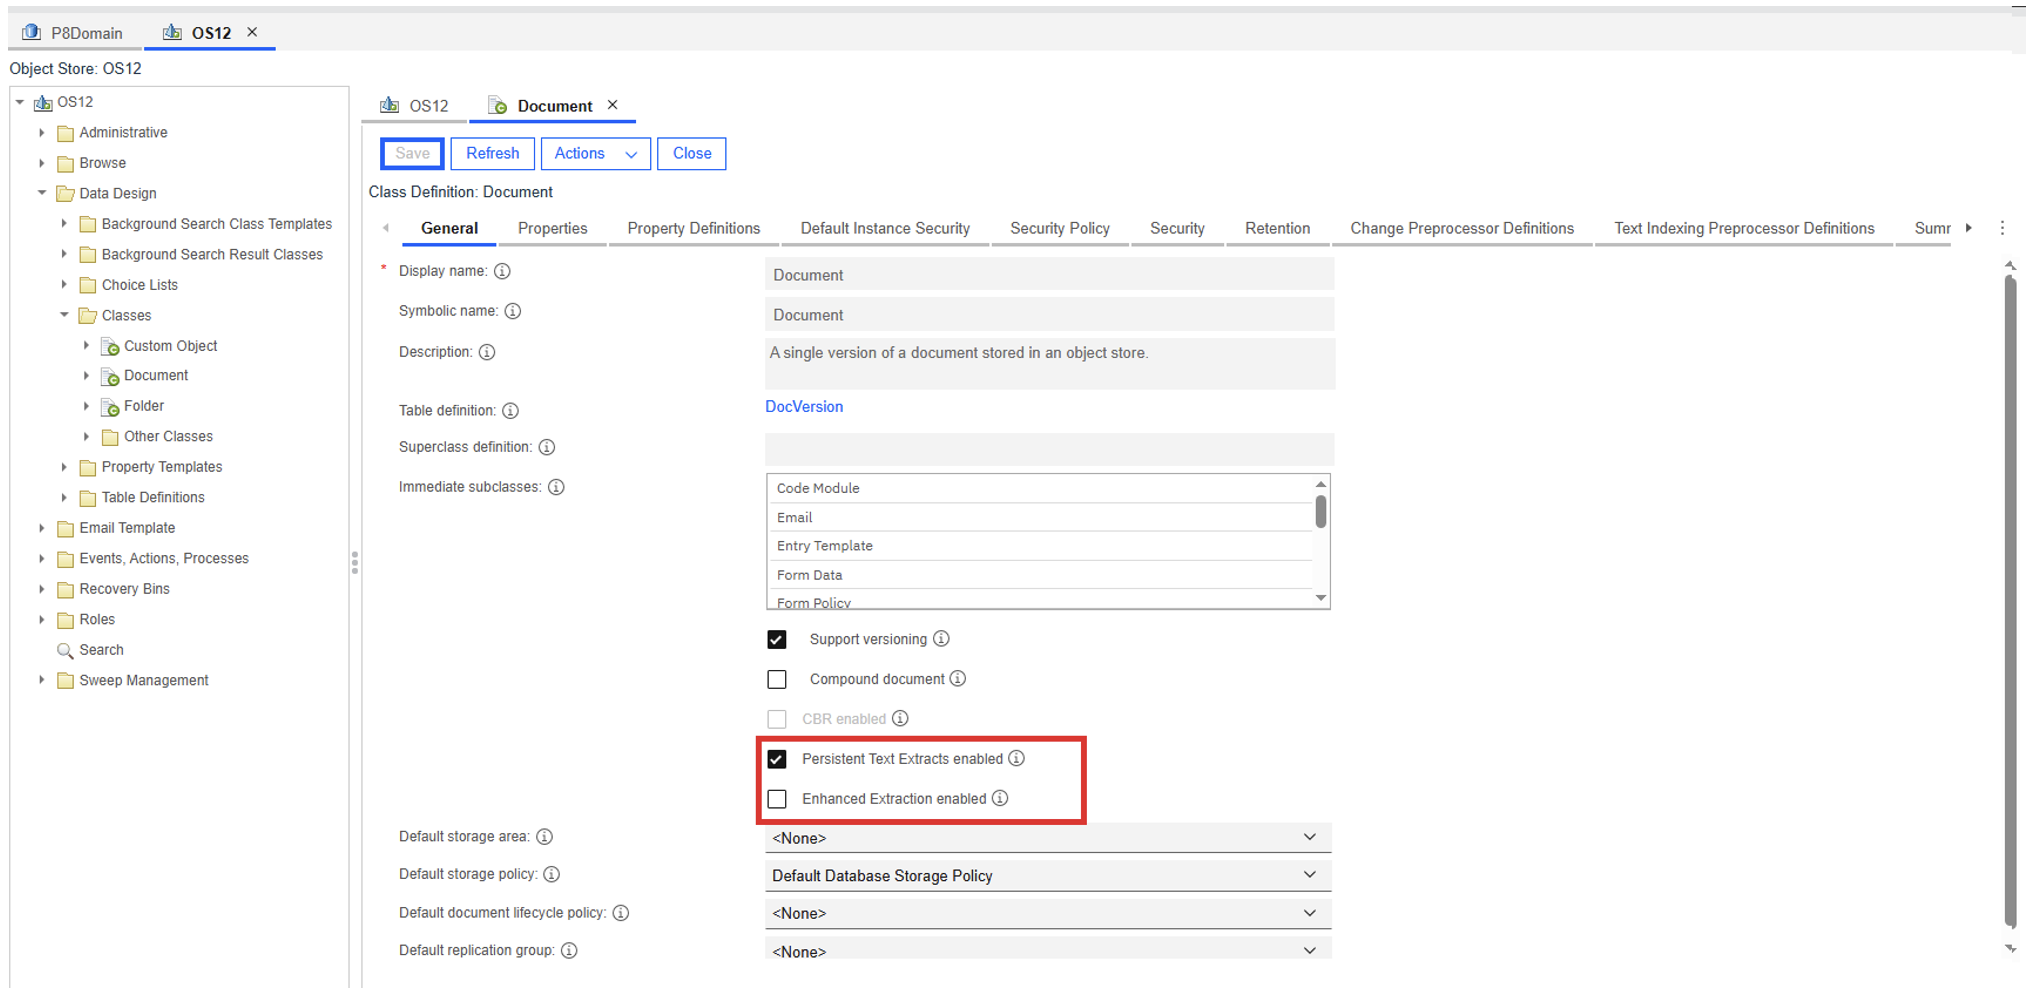
This dependency ensures that Enhanced Extraction Extension operates on top of the existing Persistent Text Extraction framework.
Step 3: Enable Enhanced Extraction Extension
-
- Select the Enhanced Extraction Enabled checkbox.
- The option will now appear as enabled for the selected document class.
By enabling this setting, the document class becomes eligible for advanced extraction processing using configured.
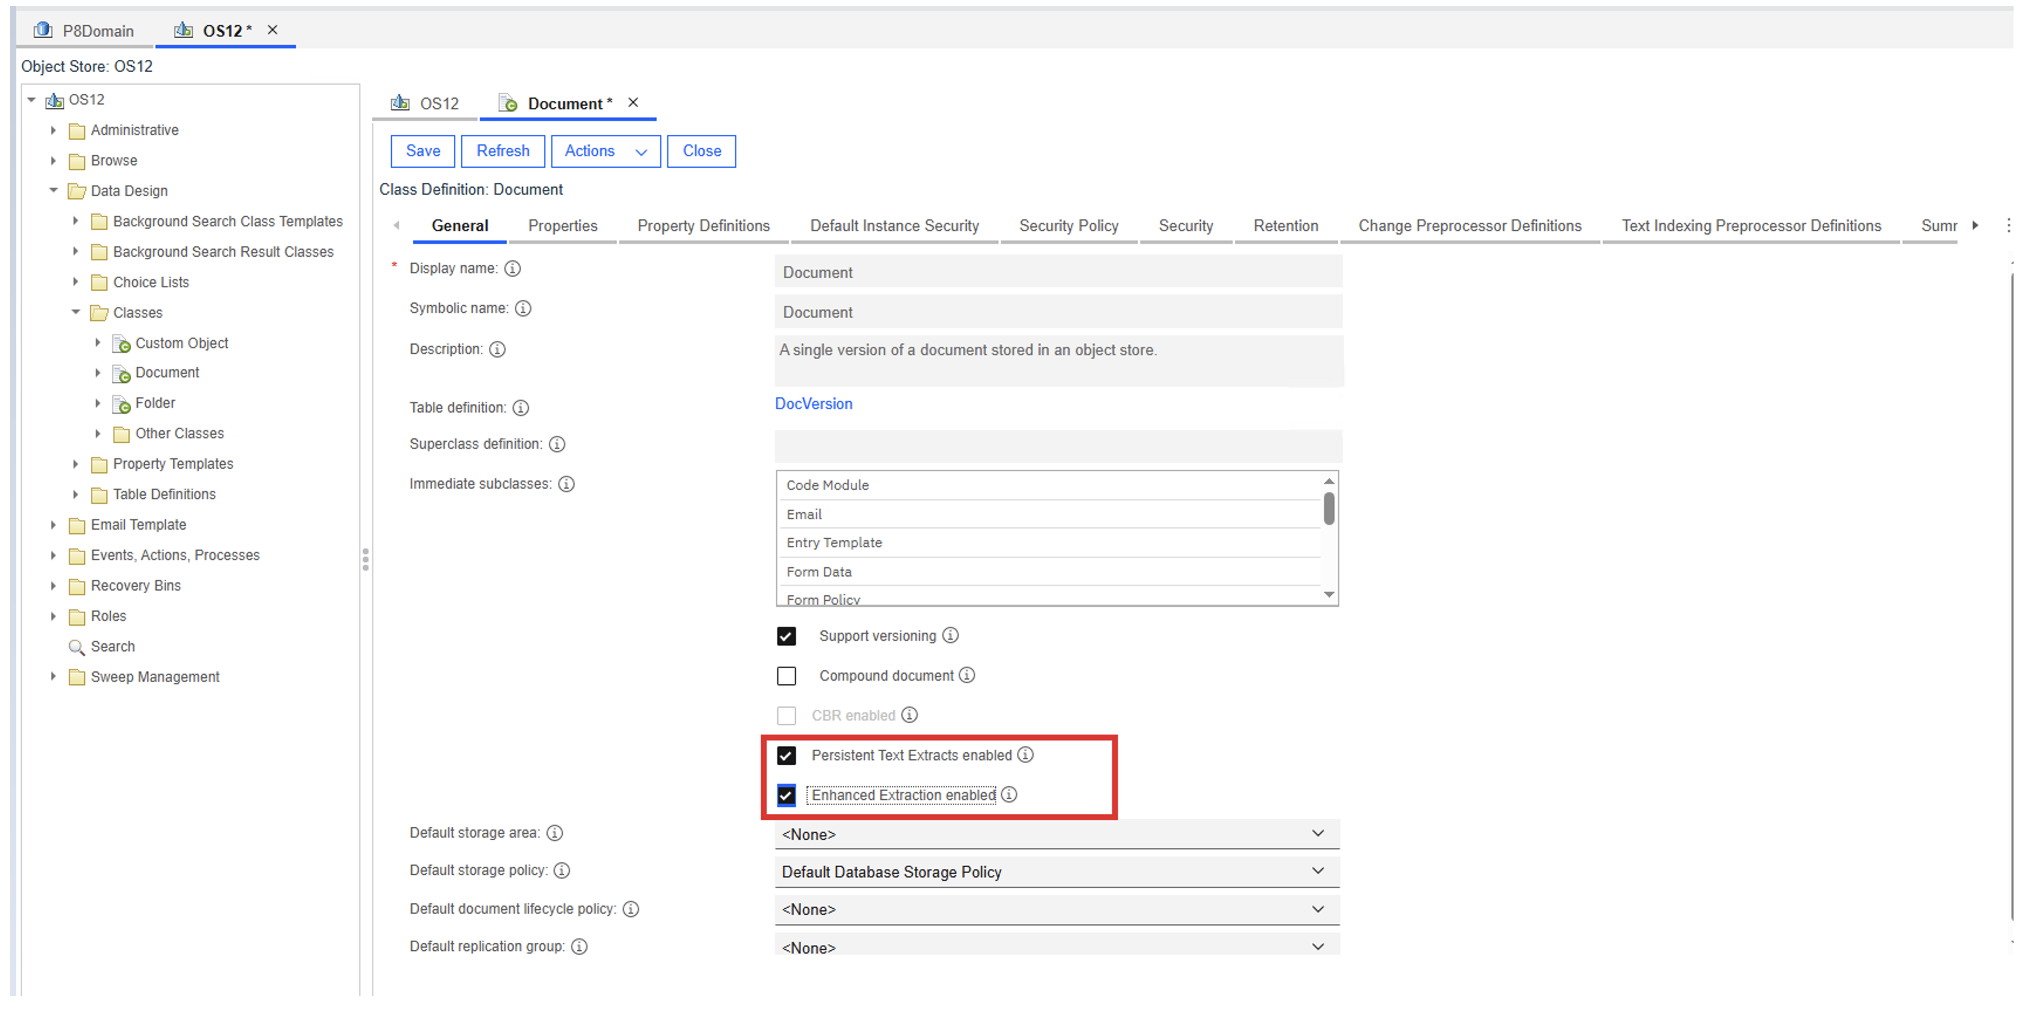
Step 4: Save the Configuration
-
- Click Save from the ACCE toolbar.
- ACCE automatically creates the required Enhanced Extraction configuration behind the scenes.
- The document class is now configured to use Enhanced Extraction Extension.
Step-by-Step Configuration of PDF Enhanced Extract Extension in ACCE
Prerequisites :
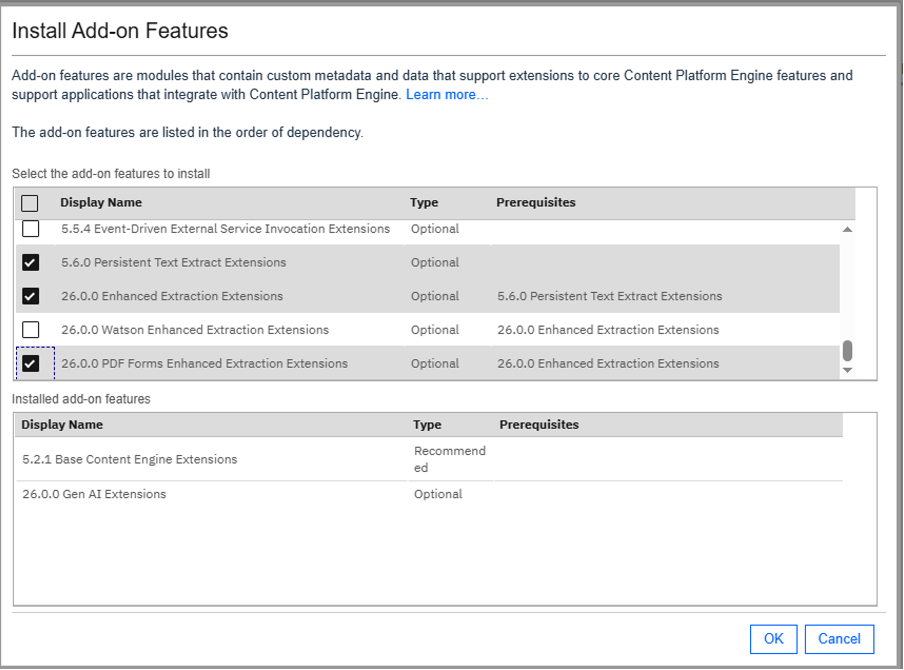
Before using the PDF Enhanced Extract, ensure the following add-ons are installed in the Object Store:
-
- Persistent Text Extraction Extensions
- Enhanced Extraction Extensions
- PDF Forms Enhanced Extraction Extensions.
Note: The PDF Forms Enhanced Extraction Extensions add-on depends on the Enhanced Extraction Extensions add-on, which in turn depends on Persistent Text Extraction.
Step 1: Install the Required Add-ons
Install the add-ons in the following order:
-
- Persistent Text Extraction Extensions
- Enhanced Extraction Extensions
- PDF Forms Enhanced Extraction Extensions
After installation, the PDF Forms Handler is automatically created and registered with the Enhanced ExtractionExtension framework.
Step 2: Verify the PDF Forms Handler
After the add-ons are installed, verify that the handler has been created successfully.
ACCE Navigation Path
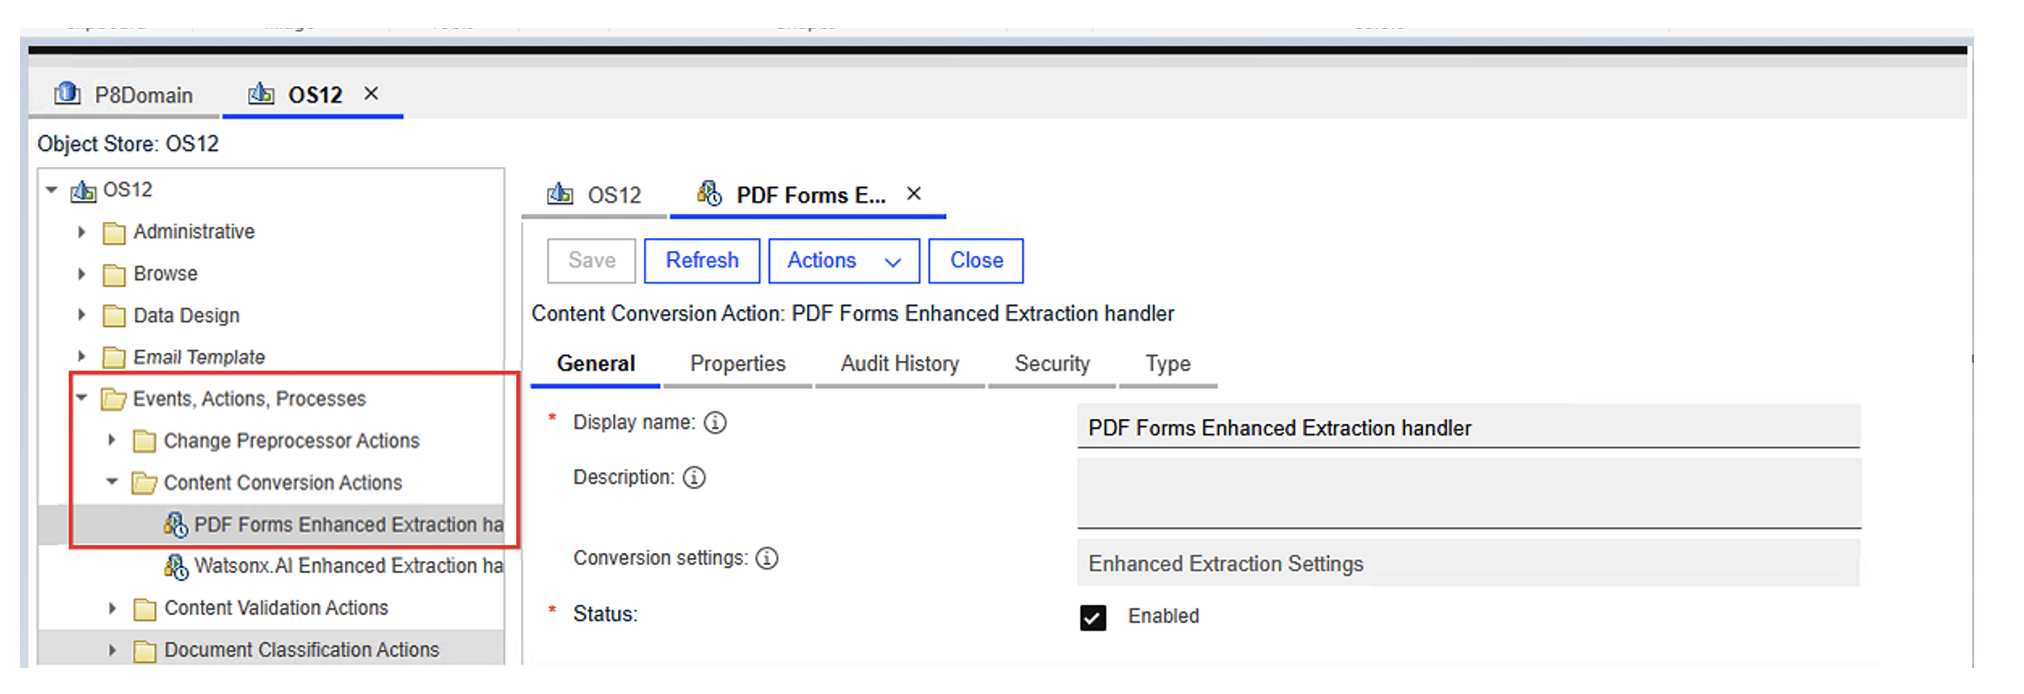
Open the handler to review its properties.
Step 3: Additional Configuration
No additional configuration is required for the PDF Forms Handler.
Step-by-Step Configuration of Watson Enhanced Extract Extension in ACCE
Step 1: Install the Required Add-ons
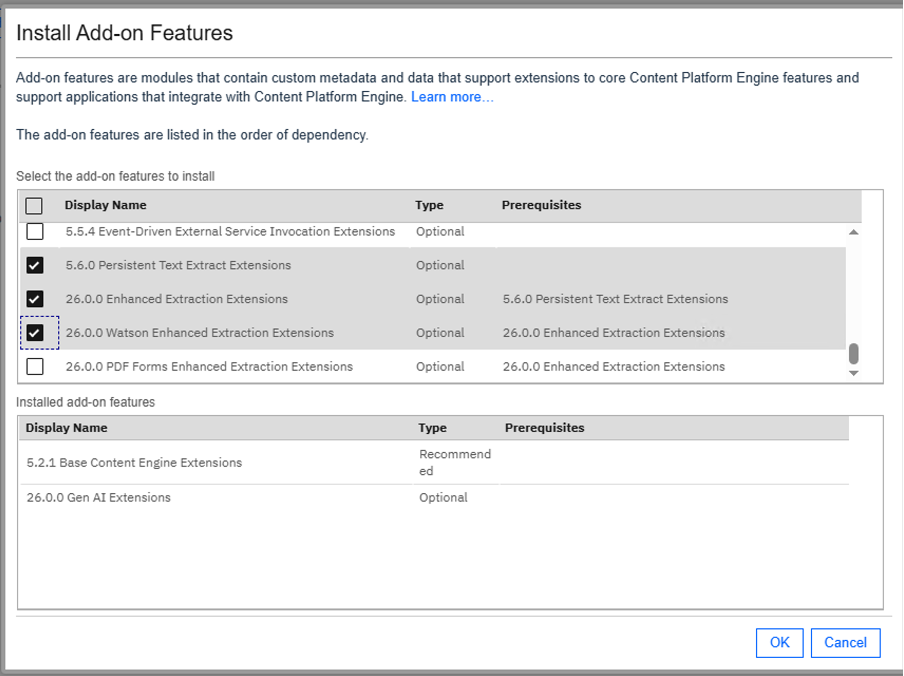
Install the add-ons in the following order:
-
- Persistent Text Extraction Extensions
- Enhanced Extraction Extensions
- Watson Enhanced Extraction Extensions
After installation, the Watsonx.AI Enhanced Extraction handler is automatically created and registered with the Enhanced Extraction Extension framework.
Step 2: Verify the Watson AI Enhanced Extract Extension Handler
After the add-ons are installed, verify that the handler has been created successfully.
ACCE Navigation Path
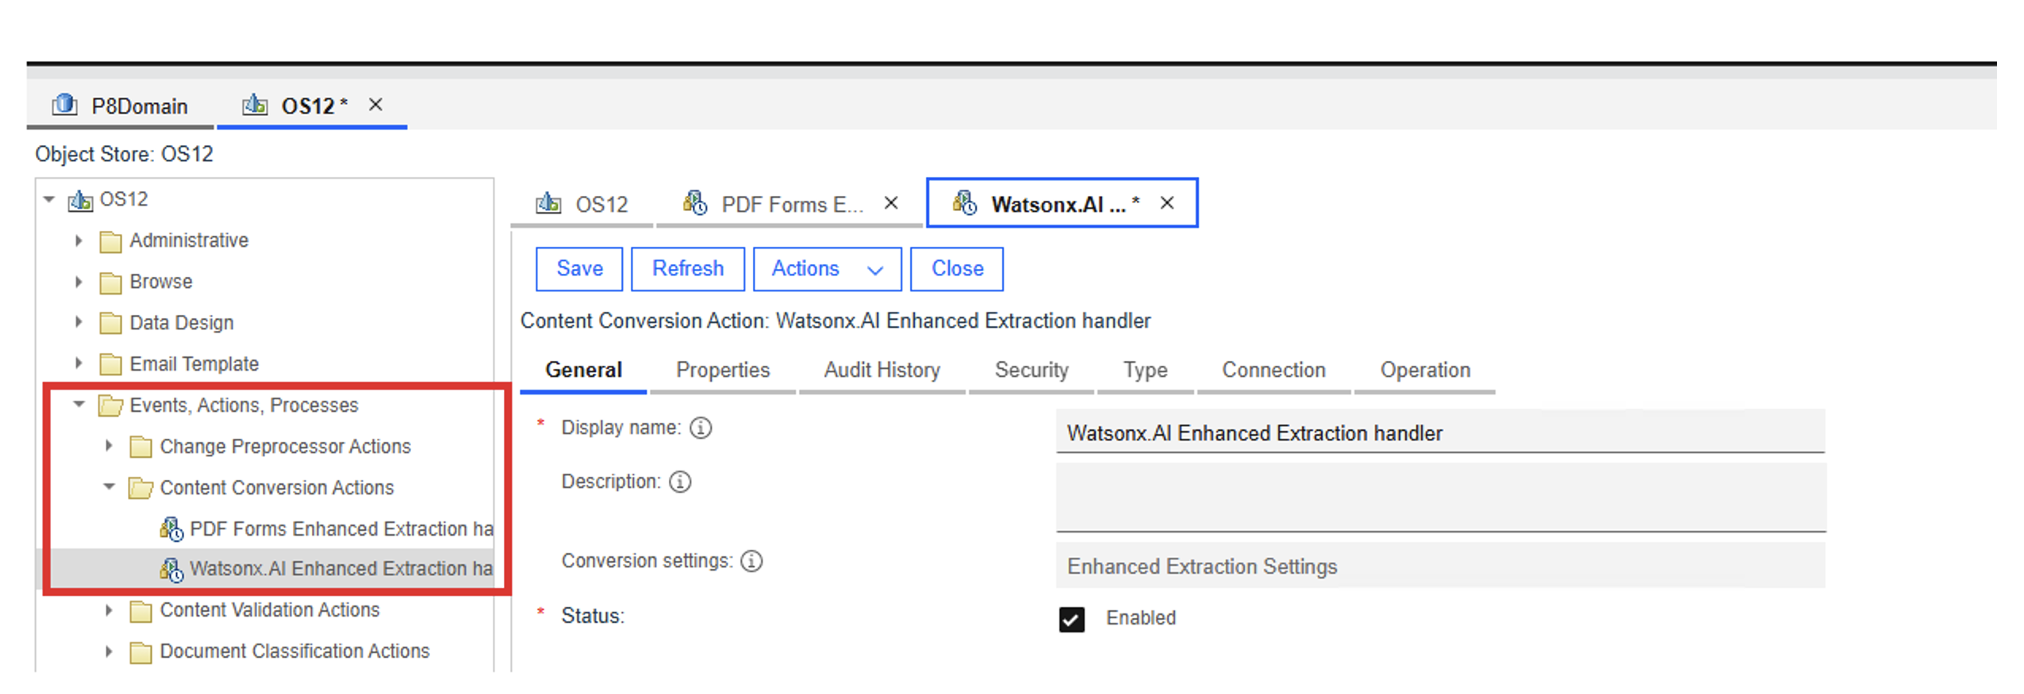
For a blog or product documentation, the content can be rewritten in a cleaner and more professional style as follows:
Step 3: Enable the Watson Enhanced Extraction Extension
-
- Open the Watson AI Enhanced Extraction Handler configuration.
- Select the Enable checkbox to activate the Watson AI Enhanced Extraction handler.
- Click Save on the toolbar to apply and persist the changes.
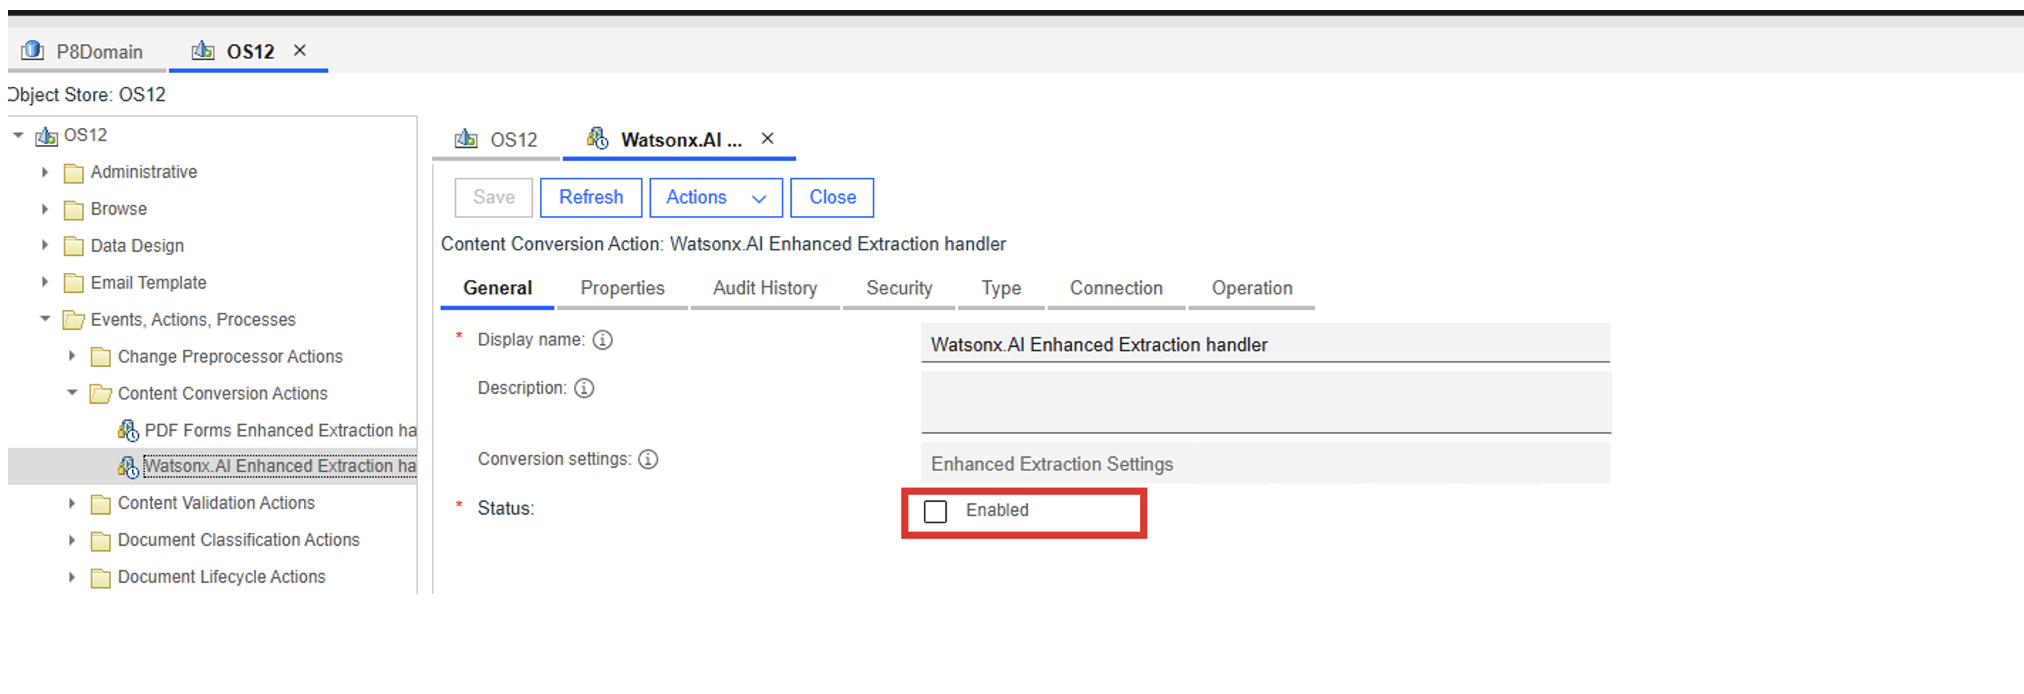
Result: The Watson Enhanced Extraction Extension is enabled and ready for configuration.
Step 4: Configure Watson Handler – Connection Settings
Location:
Object Store → Events, Actions, Processes → Content Conversion Actions
Access the Watson Handler Configuration
-
- Navigate to Events, Actions, Processes.
- Select Content Conversion Actions.
- Open Watsonx.AI Enhanced Extraction.
- Select the Connection tab.
Select the Service Type
The Watson Enhanced Extraction Handler supports two service options:
Option A: Watson Document Understanding (WDU)
-
- Select the WDU option.
- Specify the Service URL for your Watson Document Understanding environment.
- Click Save.
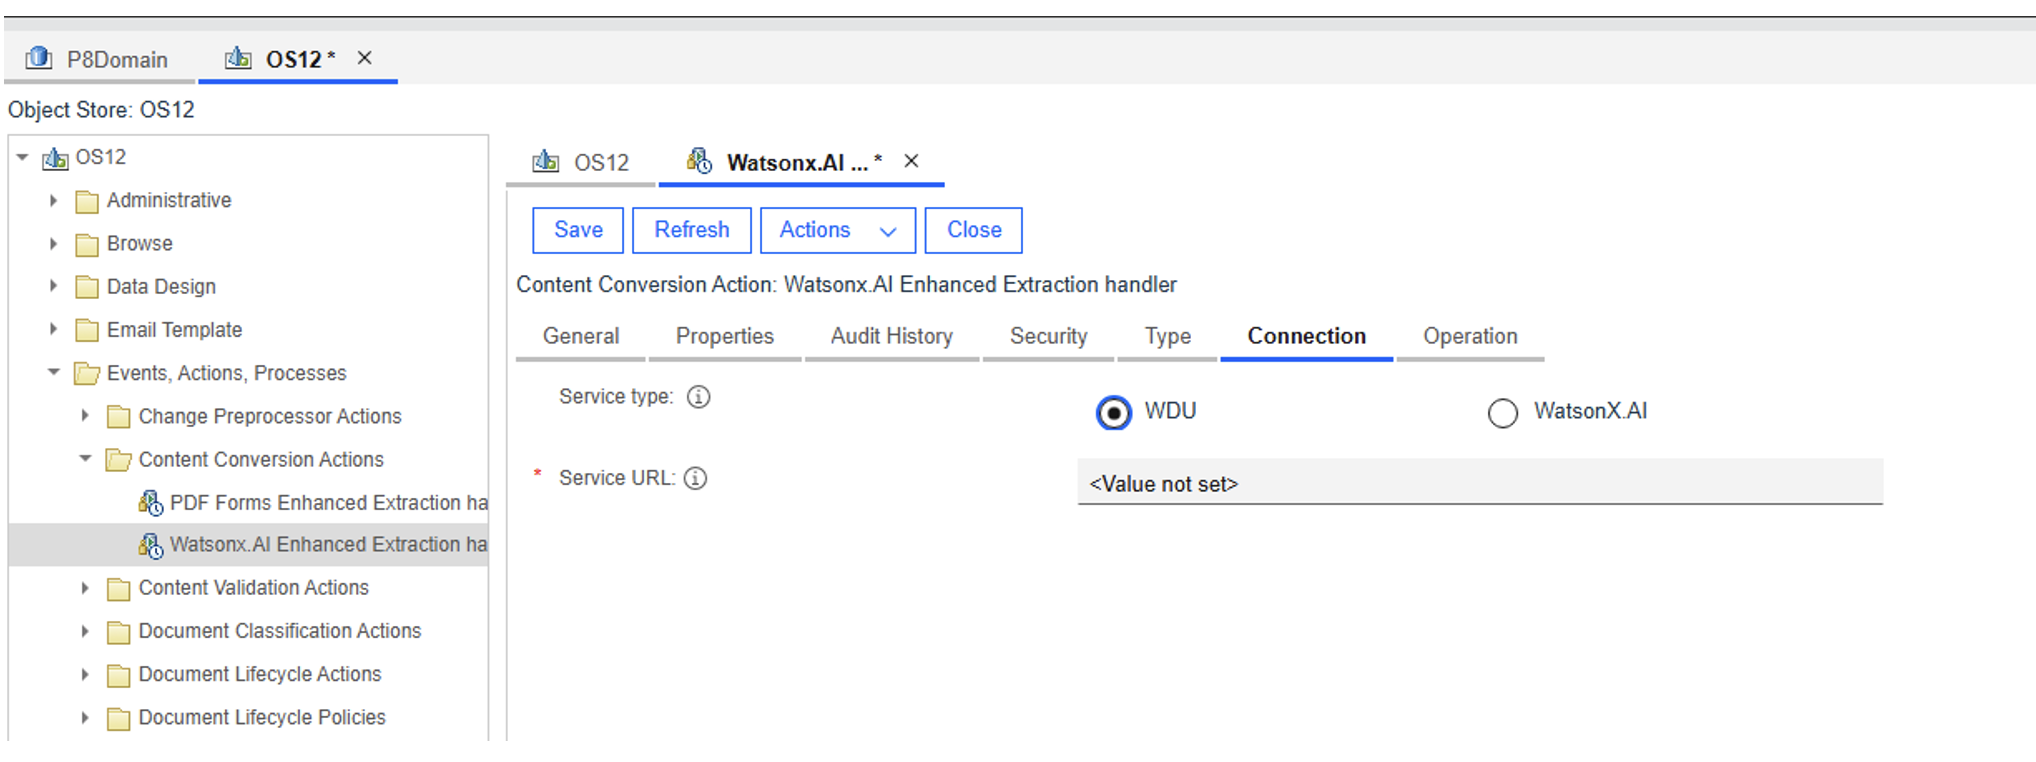
After saving the connection settings, continue with the operation configuration.
Option B: Watsonx.AI (Recommended)
- Select the Watsonx.AI option.
- Provide the required Watsonx.AI and IBM Cloud Object Storage connection details.
- Configure the following information:
-
-
|
SETTING
|
DESCRIPTION
|
|
SERVICE URL
|
Watsonx.AI service endpoint for the selected region
|
|
WATSONX API KEY
|
API key used to authenticate with Watsonx.AI
|
|
SPACE GUID
|
Watsonx.AI deployment space identifier
|
|
ICOS URL
|
IBM Cloud Object Storage endpoint
|
|
ICOS API KEY
|
API key used to access Cloud Object Storage
|
|
ICOS CONNECTION GUID
|
Cloud Object Storage connection identifier
|
- Verify that all required values are provided.
- Click Save to persist the configuration.
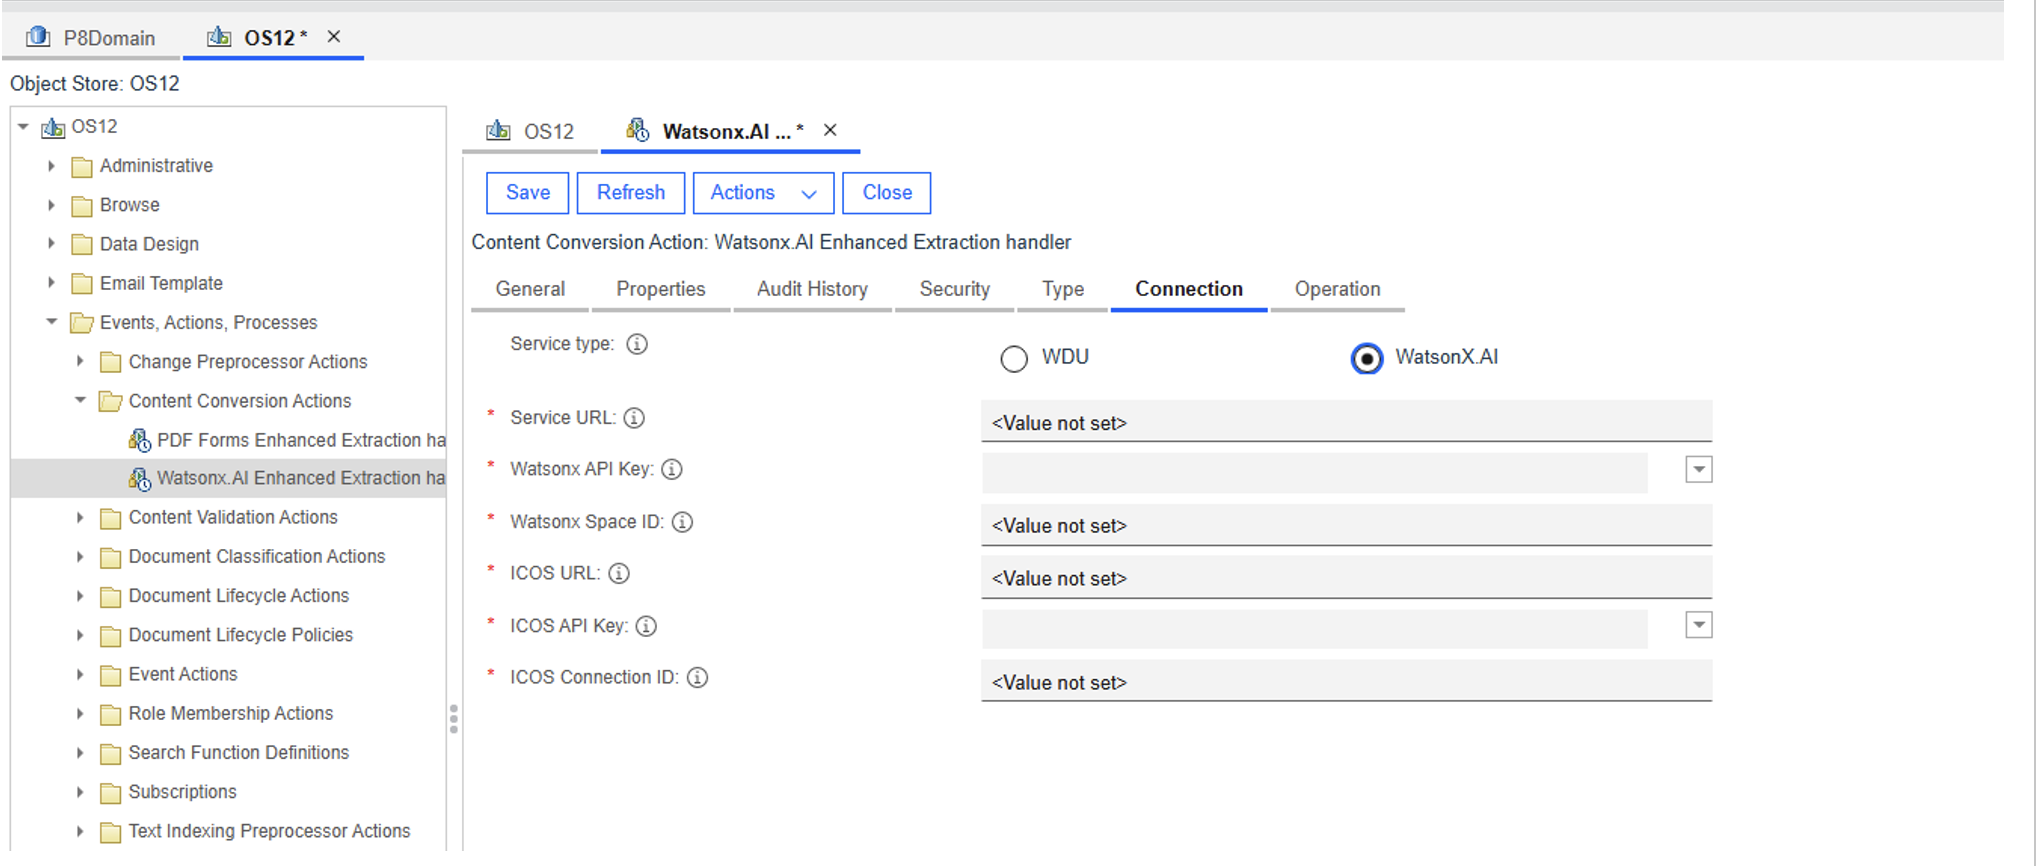
Result: The Watson Enhanced Extraction Handler is successfully connected to the selected AI service.
Step 5: Configure Watson Handler – Operation Settings
Location:
Within the same Watson Enhanced Extraction configuration dialog, select the Operation tab.
Configure Processing Mode
Choose the desired processing quality:
-
- Standard – Faster processing with reduced extraction accuracy.
- High Quality – Recommended for improved extraction quality and accuracy.
Configure OCR Mode
Select how Optical Character Recognition (OCR) should be applied:
-
- Disabled – OCR processing is not performed.
- Enabled – OCR is used when required.
- Forced – OCR is applied to all documents regardless of content type.
Configure OCR Languages
The default OCR language is configured for English document processing. To add additional languages:
-
- Click Add.
- Enter the desired language code.
- Click OK.
To remove a language:
-
- Select the language from the list.
- Click Remove.
Commonly used OCR language codes include:
|
LANGUAGE
|
CODE
|
|
ENGLISH (HANDWRITING SUPPORT)
|
en_hw
|
|
FRENCH
|
fr
|
|
GERMAN
|
de
|
|
SPANISH
|
es
|
|
JAPANESE
|
ja
|
|
CHINESE
|
zh
|
Configure Extraction Types
Select the information that should be extracted from documents
-
- Key-Value Pairs (KVPs) – Extract form fields and document metadata.
- Tables – Extract structured tabular information.
- Markdown – Preserve document hierarchy and structure in markdown format.
After completing the configuration:
-
- Review all selected options.
- Click Save.
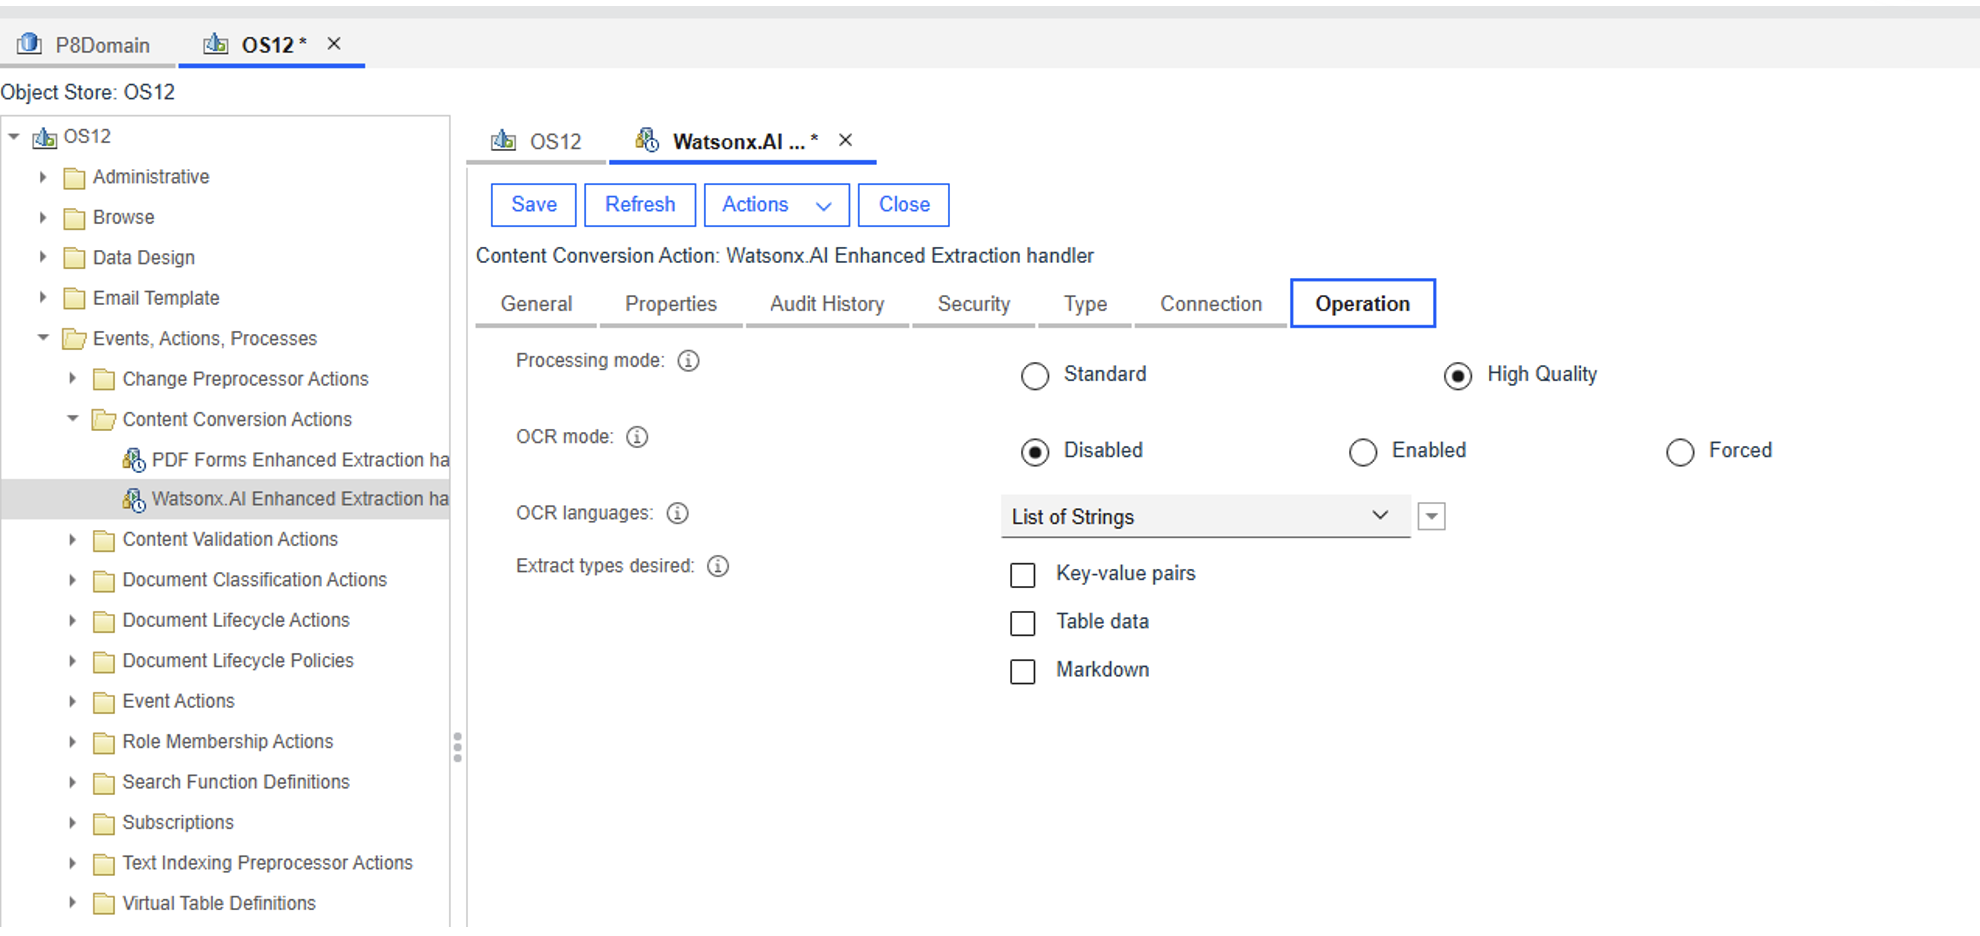
Result: The Watson Enhanced Extraction operation settings are configured and ready for document processing.